 Magoo Component UI
CSS-less skeletons · 4 themes
Magoo Component UI
CSS-less skeletons · 4 themes
image-generation-card molecule experimental A card for a single AI-generated image - the picture, its prompt, model and size, and quick actions.
The width preview needs a screen wider than the chosen width — use a larger device (or a desktop browser) to see the desktop and tablet layouts.
A neon-lit city street in the rain at night, cinematic, shallow depth of field, 35mm
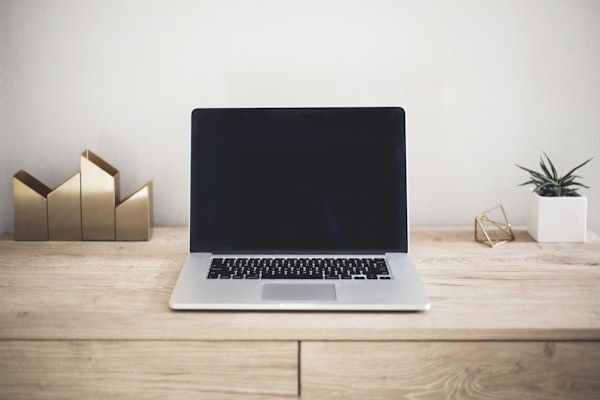
A bright minimalist desk workspace with a laptop and a small plant, soft morning light
ai/image-generation-cardname: "Image Generation Card"
short_description: A card for a single AI-generated image - the picture, its prompt, model and size, and quick actions.
long_visual_description: >
A compact card with a square cover-cropped image on top, then the generating prompt clamped to two
lines, a meta row with the model as a pill and the size in mono, and a divided action row of icon
buttons for download, regenerate, and variations.
use_cases:
- Showing an image an assistant just generated.
- A tile in a gallery of generated images.
- A result card in a text-to-image tool.
- Presenting a generation with its prompt for reuse.
- Offering download and regenerate actions on an output.
recommended_for:
- Text-to-image tools that show the prompt alongside the result.
- Any single generated image that needs quick per-item actions.
avoid_for:
- Plain content photography with no prompt or actions (use a media card).
- A dense grid where captions and actions would crowd (use a thumbnail grid).
markets:
- Global
example_usage: >
Pass image (a real path such as /stock/stage1.jpg) and the prompt; add model and size for the meta
row. Listen for the "image:action" event, whose detail.action is download, regenerate, or
variations, to wire the buttons.
how_to_use: >
behavior.js dispatches "image:action" on the card whenever an action button is clicked, with
detail.action set to the button's data-action (download, regenerate, or variations). A host app
listens for that event to perform the action. The portable self-init passes no props object.
props:
image: "Path/URL of the generated image (square, cover-cropped) and the alt source."
prompt: "The generating prompt, shown clamped to two lines and used as alt text."
model: "Optional generating model name in the meta row."
size: "Optional output size in the meta row."
example_prompts:
- "Show a generated image card with its prompt, the model, and download and regenerate buttons."
- "Add a text-to-image result card that lets the user make variations."
lifecycle: experimental
content_model: One generated image with its prompt, optional model and size, and action buttons.
theming:
tokens_used:
- --color-surface
- --color-surface-raised
- --color-on-surface
- --color-on-surface-muted
- --color-border
- --radius-card
- --radius-control
- --radius-pill
- --shadow-card
- --font-mono
- --duration-token
editorial_guidance: >
Show the full prompt in the caption so it can be copied or reused; keep the model and size terse.
Use consistent action affordances across a gallery so users learn them once.
relationships:
related:
- ai/assistant-hero
- ai/citation-list
categorization:
category: AI & Chat
subcategory: Media
atomic_type: molecule
usage_type: [card, media, grid]
maturity: ai-generated
wcag:
level: AA
notes: The image alt is the prompt text; each action button is icon-only with an aria-label; hover and focus states are visible.
keyboard_support: The three action buttons are in the natural tab order and activate on Enter/Space.
seo_score: 30
text_direction: both
| Name | Type | Req |
|---|---|---|
| image | string | ✓ |
| prompt | string | ✓ |
| model | string | |
| size | string |
behavior.js dispatches "image:action" on the card whenever an action button is clicked, with detail.action set to the button's data-action (download, regenerate, or variations). A host app listens for that event to perform the action. The portable self-init passes no props object.